How to Actually Spot AI-Generated Content
Text detectors fail, content credentials are the real fix, and one habit beats every tool. Here's what works.
On August 2, 2026, the European Union's AI Act started enforcing its transparency obligations. Providers of generative systems operating in Europe now have to mark AI output in machine readable form, deployers have to disclose deepfakes, and non-compliance can draw fines of up to €15 million or 3 percent of worldwide annual turnover. You would expect that to make the practical question easier to answer. Four weeks in, the enforcement date has changed the law, not the confusion.
The tools people reach for haven't caught up. The websites that promise to scan a block of text and tell you whether a machine wrote it are the most popular answer to this question, and they are also the least reliable part of the whole stack. Before you trust a single score from one of them, it's worth understanding why they fail, because the failure is structural and it isn't going to be patched.
Why Text Detectors Keep Failing
AI text detectors don't read for meaning. They score writing on statistical fingerprints: how predictable the word choices are, how uniform the sentence rhythm, how closely the text sits to the distribution a language model produces. A detector flags something as machine-written when its profile matches the model's habits. That sounds reasonable until you remember that language models were trained to imitate human writing in the first place, which means the two distributions overlap by design.
The overlap produces false positives at a rate that should disqualify these tools from any serious accusation. Independent benchmarks published in 2026 put false positive rates between roughly 2 and 15 percent depending on the tool, with GPTZero around 9 percent and Turnitin around 4 percent. A 9 percent false positive rate means roughly one in eleven fully human documents gets flagged. That is a polygraph you would not let near a courtroom, yet students and employees are being judged by it every week.
The fingerprint also dissolves the moment a human touches the text. Edit a few sentences, rephrase a paragraph, mix in your own voice, and the statistical signal blurs. Academic work keeps arriving at the same conclusion, including a recent study in Scientific Reports that applied the DistilBERT transformer to the detection task: machine and human text are not cleanly separable once editing is in the picture, and no detector vendor is going to advertise that.
The arms race makes the problem worse. Every new model shifts the distribution a detector is calibrated against, so a tool that scores today's output accurately is already guessing when it meets tomorrow's model. Detection is a classification problem with a moving target, and the vendors are always one generation behind.
For journalism, the detector question is also the wrong question. If a text is false, it doesn't matter whether a human or a model wrote it, the correction is the same. If a text is true, flagging it as AI tells you nothing about whether to trust it. The useful move is to fact-check the claims, verify the source, and treat the writing's origin as a separate, lower-priority question.
Content Credentials: The Receipt That Survives Edits
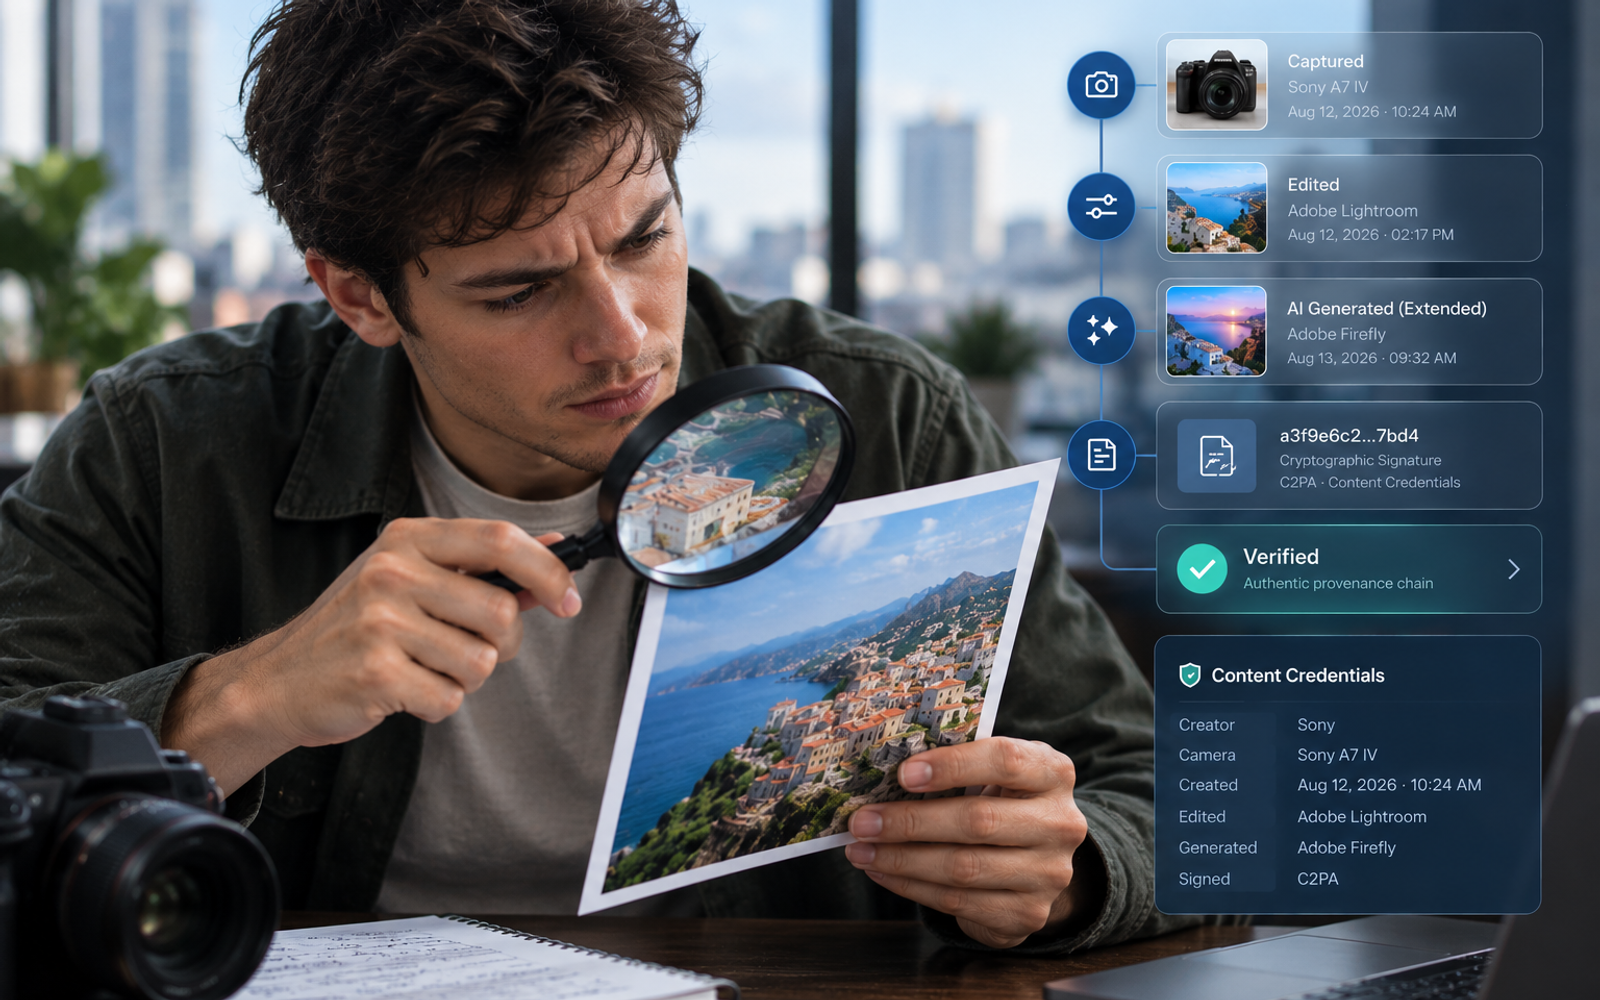
For images, there is a mechanism that actually does what detectors claim to do, and it works because it doesn't guess. Content Credentials, built on the C2PA open standard backed by Adobe, Microsoft, Google, OpenAI, Sony, and Nikon, attach a cryptographically signed record of how a piece of media was created and edited. Think of it as a passport history for a file: every border crossing, from the camera's shutter to a Photoshop edit to a save, leaves a stamp that can't be quietly removed. Anyone can inspect the chain at contentcredentials.org.
Under the hood, the mechanism is straightforward. The software that creates or edits a file computes a cryptographic hash of the pixels, signs it with a private key, and stores the record in a manifest that later tools can check against the actual file. Any change to the image breaks the hash, which makes the tampering visible even when no human eye can see it. That property is what makes it a receipt rather than a guess.
The standard moved from demo to deployment this year. OpenAI now layers C2PA metadata with its SynthID watermark across supported generated media, Google's SynthID verification is live in Gemini and expanding into Search and Chrome, and camera makers are embedding credentials at capture time. Leica's M11-P was the first camera to sign its own photos. When the EU's new rules demand machine readable marking, C2PA is the mechanism most of the industry points to.
The honest caveat is that most images online still carry no credential at all, so a missing signature proves nothing. Screenshots strip metadata, most platforms recompress uploads, and a file that has traveled through two social networks usually arrives as an orphan. Credentials are a strong signal when present and silence when absent, and treating that silence as evidence is how people get fooled in the other direction.
What Still Shows Up in the Pixels
The old visual tells are mostly gone. Modern generators stopped mangling hands, teeth, and ears, and the era of six-fingered people ended around 2024. What remains is text. AI image models still garble small lettering, street signs, product labels, and anything with precise typography, because rendering language correctly is a harder problem than rendering faces. If a sign in a supposedly real photo reads as half-legible, zoom in before you believe the scene.
Physics is the second survivor. Shadows that disagree with the light source, reflections that don't match the surface, jewelry and eyeglasses that bend in ways glass and metal don't: these errors persist because the models render appearance, not optics. A reverse image search through Google Lens or TinEye catches the third category, the composited fake, where a real photograph has AI elements pasted in and the search turns up the original event photo without them.
There is also an aesthetic worth learning to recognize. A large share of AI-generated social content, the glossy, hyper-saturated, generically inspirational posts that now flood professional networks, shares a look engineered to be liked rather than read. It's not proof of anything by itself, but it's a reliable cue to slow down and check the other signals.
The Habit That Beats Every Tool
The most useful verification guidance to come out of investigative journalism in the past year has converged on a simple move: stop asking whether content is AI and start asking who made it and whether they are accountable. A named photographer at a wire agency, a reporter with a byline and an editor, an institution with a reputation on the line: these are the only entities that lose something when they are wrong. Anonymous accounts and unbylined pages have nothing to lose, and that is the real risk factor, not the model underneath.
This is why the EU labelling rules matter even though they are imperfect. From August 2, every generative tool operating in Europe has to mark its output in machine readable form, which means you can now check any new piece of content for a credential and see who signed it. The absence of an answer becomes meaningful over time, as long as the platform preserves the metadata in the first place. The European Commission's guidance on the transparency obligations makes clear the burden lands on both providers and deployers.
In practice, that means building a two-step reflex. On anything visual, run the reverse image search and check for credentials. On text, skip the detectors and verify the claims against the primary source, the same discipline that applies to the writing tools themselves. Our earlier comparison of Claude, ChatGPT, and Gemini found the real differences between those models show up in what they produce, not in how detectable it is.
The education world is learning this the hard way. With nearly 90 percent of students saying they have used AI in academic work and 53 percent using it at least weekly, universities that leaned on detectors have spent the past year walking back false accusations. The institutions that handled it well moved to process checks instead: asking students to explain their work, comparing writing across assignments, and verifying citations, all of which test understanding rather than guessing at authorship.
Read Also
The Flag Went Up. Now What?Where the Provenance Chain Still Breaks
The system has real limits, and a 2026 security analysis of the C2PA specifications concluded that the current protocols fail to achieve their claimed security goals, with trust chains and adversarial removal among the weak points. Metadata gets stripped in transit, credentials don't survive screenshots, and an attacker generating a deepfake is not going to attach a label saying so. Provenance is a cooperative system in a world full of non-cooperative actors.
For audio and video, the picture is grimmer. Voice cloning is cheap enough that a convincing deepfake costs almost nothing to produce, and the forensic tools that exist, watermark detection and waveform analysis, only work when the generator cooperates or the artifacts survive compression. The EU's new rules force deployers to label deepfakes, which catches the cooperative ones and does nothing about the adversarial ones.
The machine readable requirement of the AI Act also has a human problem: a cryptographic signature is invisible to the eye. Nothing about a credentialed image looks different on screen, and the average person scrolling a feed is not going to open a verifier. The label protects the person who checks, and most people won't check, which is exactly the gap the next round of misinformation will aim at.
Looking at the whole stack, I'd argue the industry is pouring effort into the wrong end of the problem. Detection models are a dead end for text, and image detectors are a whack-a-mole race against generators that improve monthly. The durable fix is provenance infrastructure, and its bottleneck is metadata survival: whether a credential can travel from creation to a viewer's screen through screenshots, recompression, and hostile platforms without being torn off.
The technical question that remains open is metadata survival. A cryptographic signature is only as good as its journey: it has to endure the screenshot, the re-upload, the re-encode, and still tell the viewer who made the thing and when, and no standard has solved that yet. Until one does, the practical guide stays short: check who made it, check what else they made, verify the claims against a primary source, and treat every detector score as a suggestion rather than a verdict.
Comments (0)
No comments yet. Be the first to share your thoughts.